Engineering
Python, SQL, PySpark and Spark workflows for ingestion, cleansing, transformation, enrichment and reconciliation.
Data Engineer focused on Python, SQL, PySpark, Apache Spark, Azure Databricks, ETL/ELT, data quality and production-grade analytics workflows.
My work spans enterprise ETL, data validation, reconciliation, distributed processing, analytics products and cloud modernization. I focus on traceable pipelines, clean data contracts, operational reliability and useful business outcomes.
Python, SQL, PySpark and Spark workflows for ingestion, cleansing, transformation, enrichment and reconciliation.
Azure Data Factory, Azure Databricks, Azure Data Lake, AWS S3 and AWS Glue/Lambda/Redshift exposure.
Schema checks, null validation, business rules, source-to-target reconciliation, retries and operational runbooks.
Power BI, DAX, SQL analytics and data products that turn curated datasets into business-facing KPIs.
Enterprise investment-data ETL covering ingestion, cleansing, reconciliation, analytics and modernization across Azure and AWS data sources.
High-volume ETL and analytical preparation for customer behavior, churn features, data quality and Power BI reporting.
A production-oriented blueprint for global stock, ETF, index and financial data using streaming + daily batch, Kafka/MSK, Spark, S3, Airflow/MWAA, data quality, governance and automated reporting.
Transaction analytics and PySpark ETL for customer segmentation, cohort trends, conversion, AOV and anomaly monitoring.
This gallery captures the architecture evolution: ingestion, Kafka/MSK, Spark, bronze/silver/gold layers, orchestration, quality, governance, CI/CD, DR and cost controls.
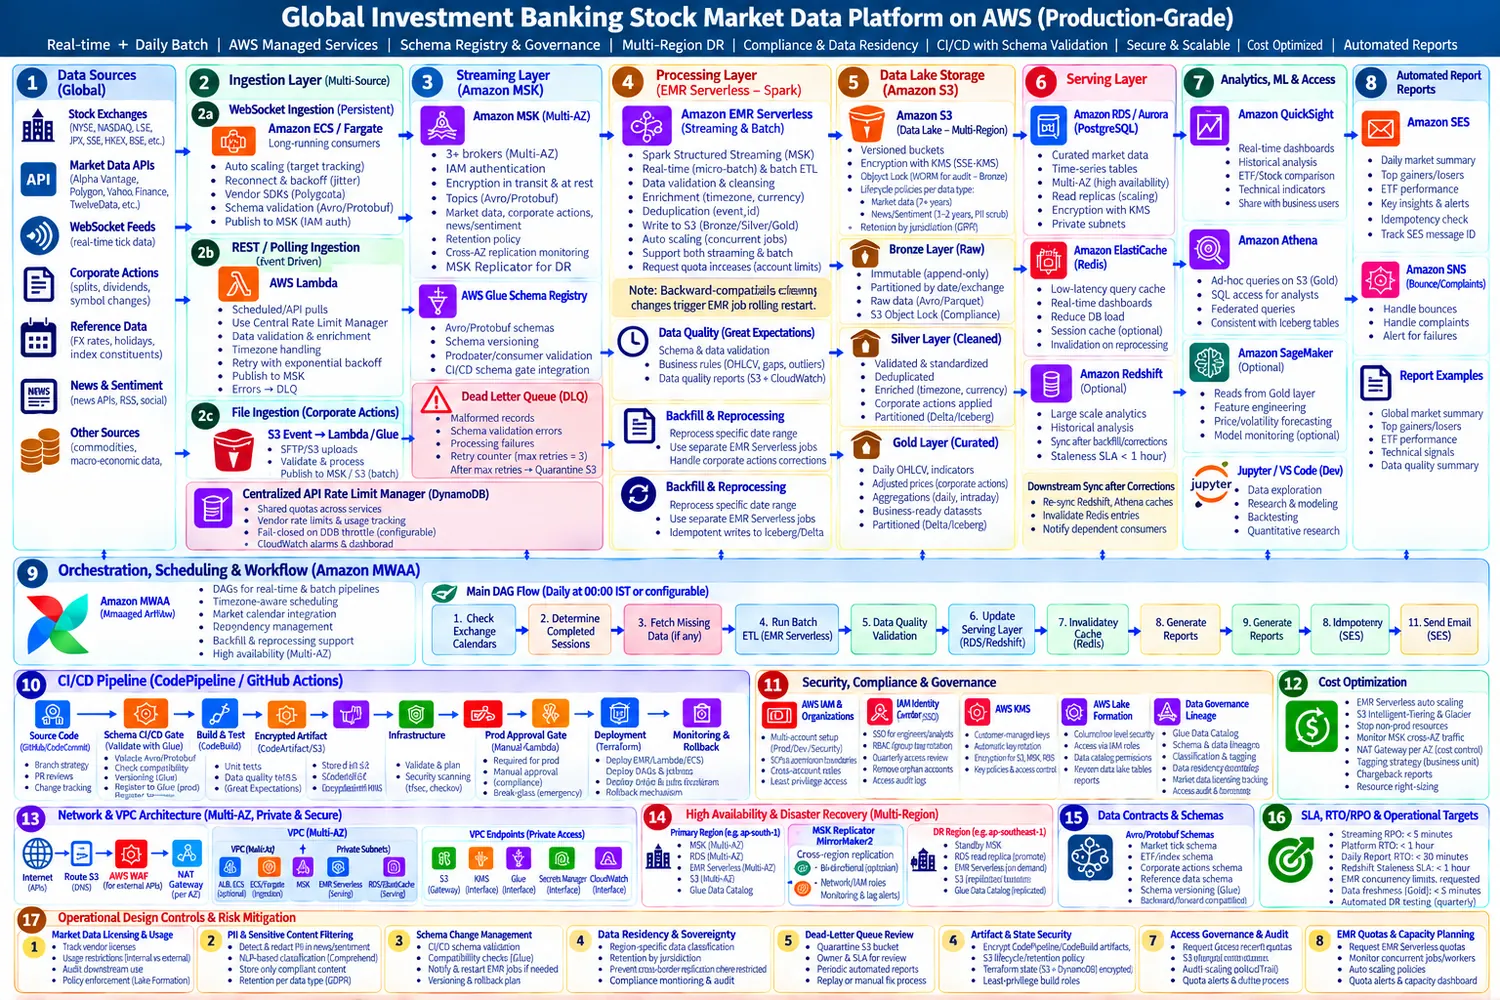
Real-time + daily batch architecture with AWS managed services, schema registry, DLQ/retry, idempotency, timezone handling, backfill, security, governance, high availability, multi-region DR and automated email reports.
Initial streaming + batch design using Python ingestion, Kafka, Spark, HDFS/MinIO, PostgreSQL, Airflow and analytics tooling.
AWS-managed mapping for ingestion, streaming, processing, S3 lake storage, serving and analytics.
Adds DLQ, retries, idempotency, checkpointing, timezone-aware scheduling and reprocessing controls.
Introduces source control, build/test, encrypted artifacts, infrastructure deployment, approval and rollback.
Adds schema validation, approval gates, API rate limits, governance and production safeguards.
Strengthens API quota management, compliance, access governance, data residency and artifact security.
Event-driven ingestion with Lambda/EventBridge patterns for file arrival, retries and operational notifications.
Multi-layer data lake, serving, analytics, MWAA orchestration, monitoring, security and DR.
Production-grade global investment banking market-data platform with real-time + daily batch, governance, DR and automated reports.
Bachelor of Arts (Economics), University of Pune.
For Data Engineer roles, ETL/ELT projects, cloud data platforms, analytics engineering or architecture discussions, send a message through the form.