DATA ENGINEERING • PUNE, INDIA

Building reliable
data platforms
from source to insight.

Data Engineer focused on Python, SQL, PySpark, Apache Spark, Azure Databricks, ETL/ELT, data quality and production-grade analytics workflows.
3+ yrsCore Data Engineering
Financial ServicesPortfolio Analytics
Python + SQLPySpark / Spark
Pranay Sarode Data Engineering logo
Azure Databricks
AWS • Spark • Kafka
ETL / ELT • DQ • CI/CD
01 / ABOUT

Data engineering with a production mindset.

My work spans enterprise ETL, data validation, reconciliation, distributed processing, analytics products and cloud modernization. I focus on traceable pipelines, clean data contracts, operational reliability and useful business outcomes.

⚙

Engineering

Python, SQL, PySpark and Spark workflows for ingestion, cleansing, transformation, enrichment and reconciliation.

☁

Cloud & Platforms

Azure Data Factory, Azure Databricks, Azure Data Lake, AWS S3 and AWS Glue/Lambda/Redshift exposure.

✓

Quality & Reliability

Schema checks, null validation, business rules, source-to-target reconciliation, retries and operational runbooks.

▦

Analytics

Power BI, DAX, SQL analytics and data products that turn curated datasets into business-facing KPIs.

02 / EXPERIENCE

Enterprise data engineering experience.

Mar 2021 — Nov 2024 · Pune

Infosys Limited — Data Engineer

Capital Group Portfolio Analytics · Financial Services
  • Built PySpark, Python and SQL ETL workflows for high-volume investment datasets across CSV, JSON, Parquet, Azure Data Lake and AWS S3.
  • Implemented schema validation, null checks, business-rule validation and source-to-target reconciliation for quality-controlled deliverables.
  • Optimized SQL Server analytics for NAV, risk, fund performance and KPI reporting.
  • Supported modernization of legacy sources into a centralized Azure analytics platform using Azure Databricks.
  • Automated reporting and deployment activities with Python, Git and Jenkins.
Mar 2021 — Nov 2022 · Pune

Infosys Limited — Data Engineer

Broadband Customer Churn Analytics · Telecommunications
  • Built PySpark ETL for telecom usage, demographic, CSV, Parquet, JSON and log data.
  • Developed SQL transformations using joins, CTEs and window functions for churn features and customer behavior indicators.
  • Implemented ETL testing across data-lake and warehouse layers.
  • Used SSIS for scheduled batch movement and supported CI/CD delivery.
  • Built churn analysis and Power BI dashboards for risk segments and KPIs.
May 2019 — Feb 2021 · Pune

Mphasis Limited — MIS Executive / Data Analyst

Klarna US Customer Behavior & Fintech Analytics
  • Analyzed transaction data with SQL and Python for spend behavior, cohorts and customer segments.
  • Built PySpark workflows from AWS S3/Azure Blob Storage into analytical datasets.
  • Applied schema checks, null handling and reconciliation controls.
  • Built Power BI dashboards and predictive customer-behavior analysis.
03 / TECHNICAL STACK

The tools I use to move data reliably.

Programming & Processing

PythonSQLPySparkApache SparkScala

Azure

Azure Data FactoryAzure DatabricksADLSBlob Storage

AWS

S3GlueLambdaRedshiftEMRMSK

Data Engineering

ETL / ELTBatchStreamingData QualityReconciliationDimensional Modeling

Data Platforms

KafkaAirflowDelta LakeIcebergHadoop HDFSTrino

Databases & BI

SQL ServerMySQLPostgreSQLPower BIDAXTableau

DevOps & Delivery

Git / GitHubJenkinsCI/CDDockerAgile / Scrum

Observability

PrometheusGrafanaCloudWatchRunbooksAuditability
04 / PROJECTS

Projects that connect engineering to business outcomes.

02
TELECOMMUNICATIONS

Broadband Customer Churn Analytics

High-volume ETL and analytical preparation for customer behavior, churn features, data quality and Power BI reporting.

PySparkSQLSSISPower BIML
03
PERSONAL ARCHITECTURE PROJECT

Global Investment Banking Market Data Platform

A production-oriented blueprint for global stock, ETF, index and financial data using streaming + daily batch, Kafka/MSK, Spark, S3, Airflow/MWAA, data quality, governance and automated reporting.

Kafka / MSKSparkS3Airflow / MWAAPostgreSQLRedis
04
FINTECH ANALYTICS

Klarna US Customer Behavior

Transaction analytics and PySpark ETL for customer segmentation, cohort trends, conversion, AOV and anomaly monitoring.

PythonSQLPySparkAWS S3Power BI
05 / ARCHITECTURE GALLERY

From concept to production-grade market-data platform.

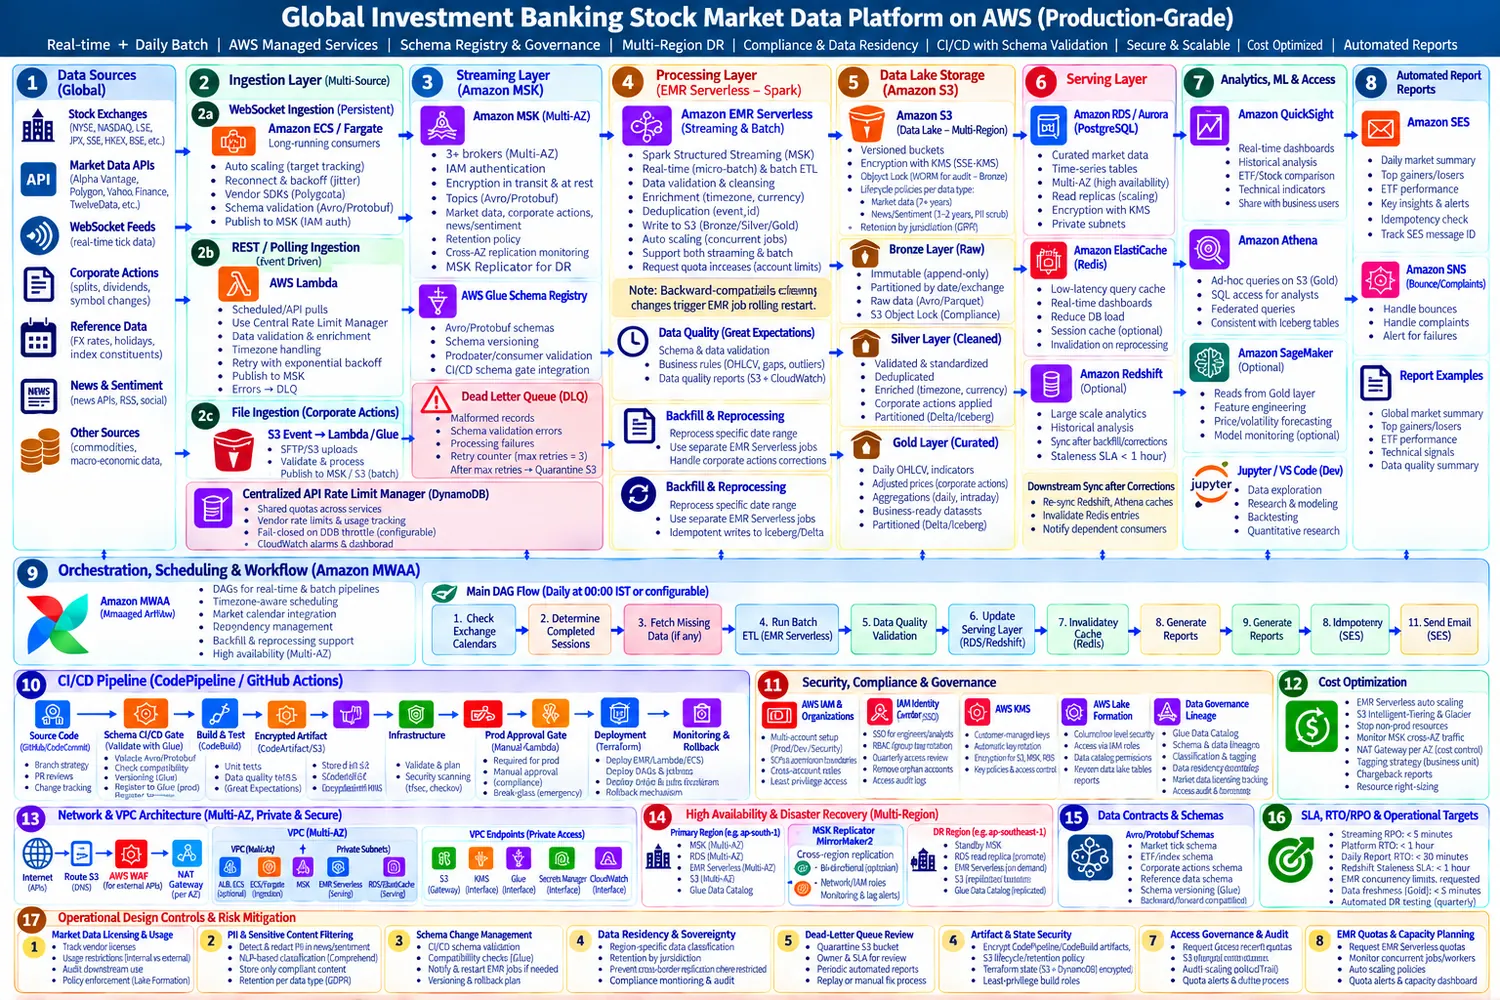
This gallery captures the architecture evolution: ingestion, Kafka/MSK, Spark, bronze/silver/gold layers, orchestration, quality, governance, CI/CD, DR and cost controls.
01 — Core Market Data Architecture

Initial streaming + batch design using Python ingestion, Kafka, Spark, HDFS/MinIO, PostgreSQL, Airflow and analytics tooling.

02 — AWS Native Mapping

AWS-managed mapping for ingestion, streaming, processing, S3 lake storage, serving and analytics.

03 — Reliability & Backfill

Adds DLQ, retries, idempotency, checkpointing, timezone-aware scheduling and reprocessing controls.

04 — CI/CD & Deployment

Introduces source control, build/test, encrypted artifacts, infrastructure deployment, approval and rollback.

05 — Operational Risk Controls

Adds schema validation, approval gates, API rate limits, governance and production safeguards.

06 — Rate Limits & Governance

Strengthens API quota management, compliance, access governance, data residency and artifact security.

07 — Event-Driven Variant

Event-driven ingestion with Lambda/EventBridge patterns for file arrival, retries and operational notifications.

08 — Near-Production AWS Platform

Multi-layer data lake, serving, analytics, MWAA orchestration, monitoring, security and DR.

09 — Final Production Blueprint

Production-grade global investment banking market-data platform with real-time + daily batch, governance, DR and automated reports.

06 / FOUNDATION

Education & certifications.

Bachelor of Arts (Economics), University of Pune.

IBM Data Analyst Professional CertificateCoursera
Data Science & Analytics SpecialistITVEDANT
Hardware & Networking TechnicianSilicon Valley Institute
07 / CONTACT

Let's talk about data engineering.

For Data Engineer roles, ETL/ELT projects, cloud data platforms, analytics engineering or architecture discussions, send a message through the form.

Your message is stored securely in the site's contact inbox. No third-party form service is required.